An 80-Run Benchmark of AI Login Agents
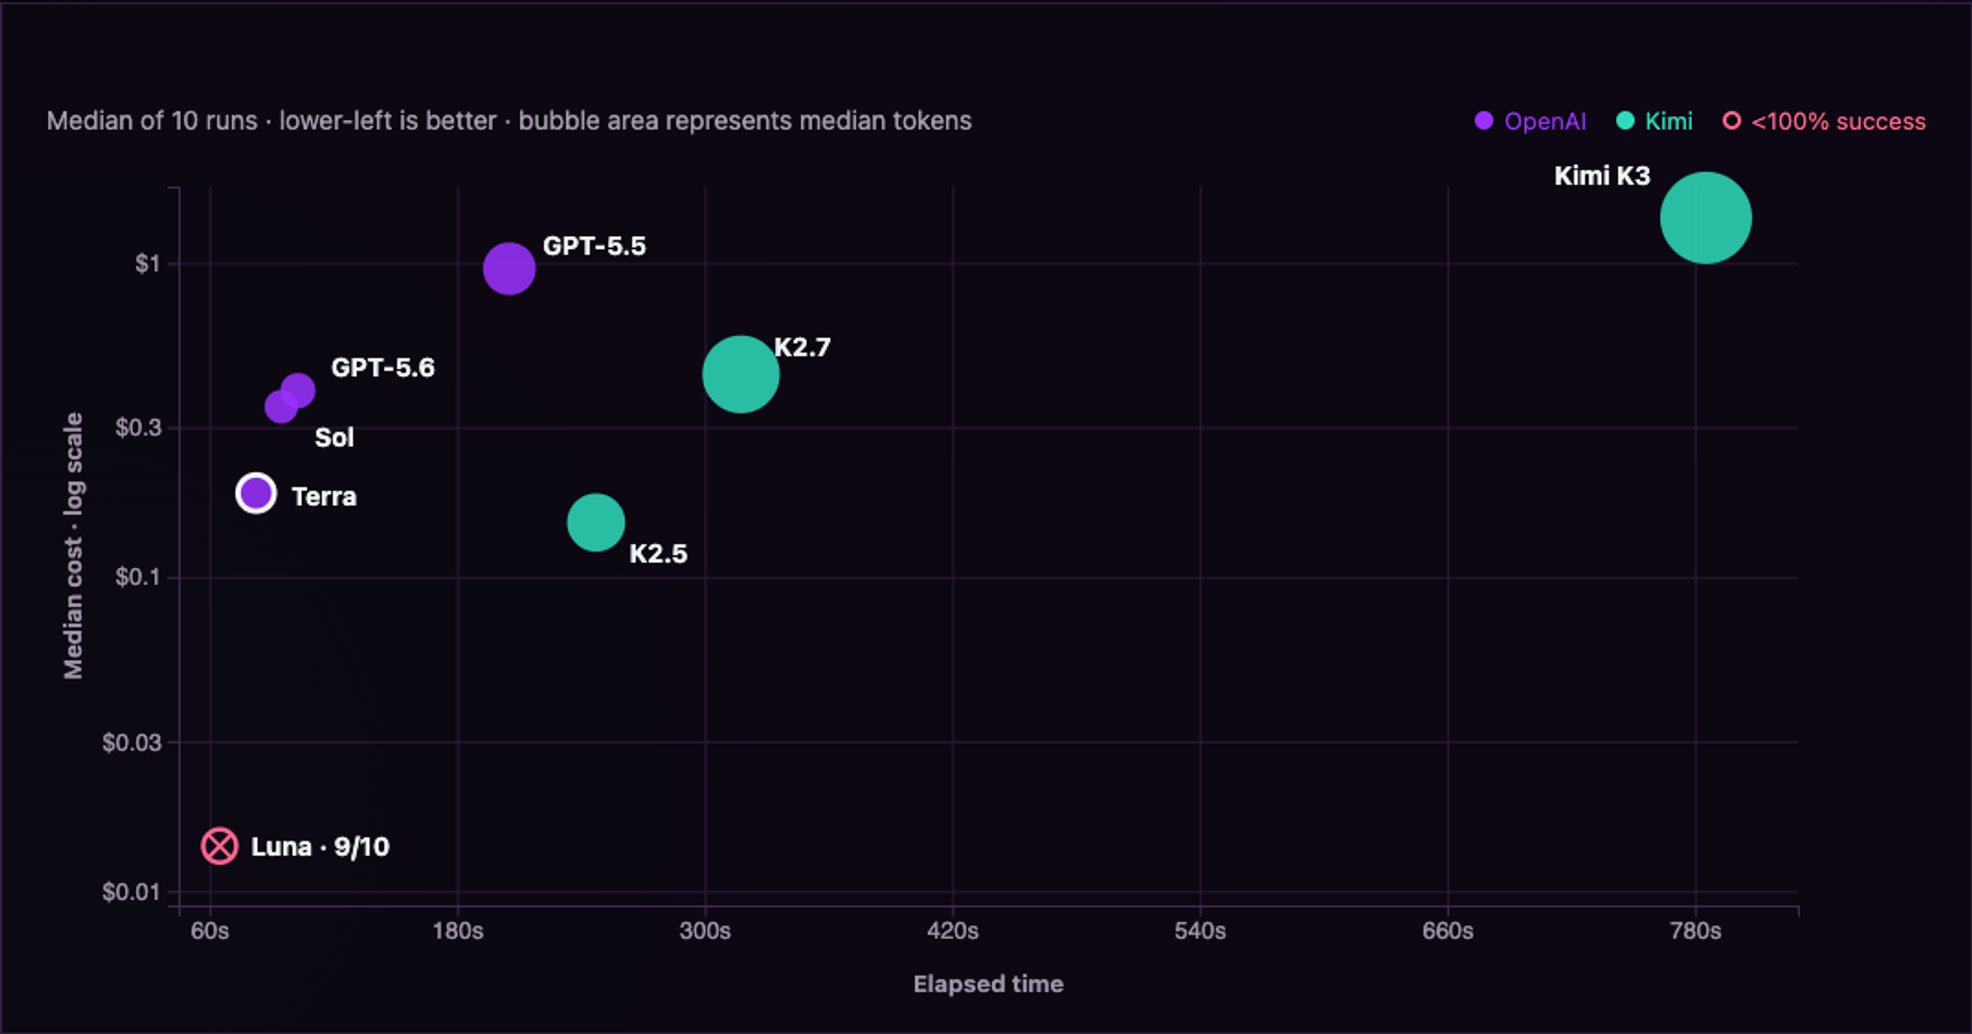
Eight models ran the same five-user login task 10 times. We measured authentication success, cost, latency, tokens, and execution strategy.
Eight models ran the same five-user login task 10 times. We measured authentication success, cost, latency, tokens, and execution strategy.
Most AI security systems constrain every attack agent. We take a different approach: let some agents explore widely, then rely on a downstream verifier to keep only what is real.
Insight: Exploration and verification work better when different agents own each job.
A daemon-thread watchdog that escalates through five correction tiers (nudge, redirect, force-wrap, hard stop, terminate) to stop AI pentesting agents from drifting without cutting off legitimate work.
Insight: Long-horizon agents need live drift correction before budget is gone.
We pair every AI testing agent with a second agent that independently re-exploits each finding using statistical verification and drops anything it can't reproduce.
Insight: AI findings need independent re-exploitation before they reach a report.