An 80-Run Benchmark of AI Login Agents
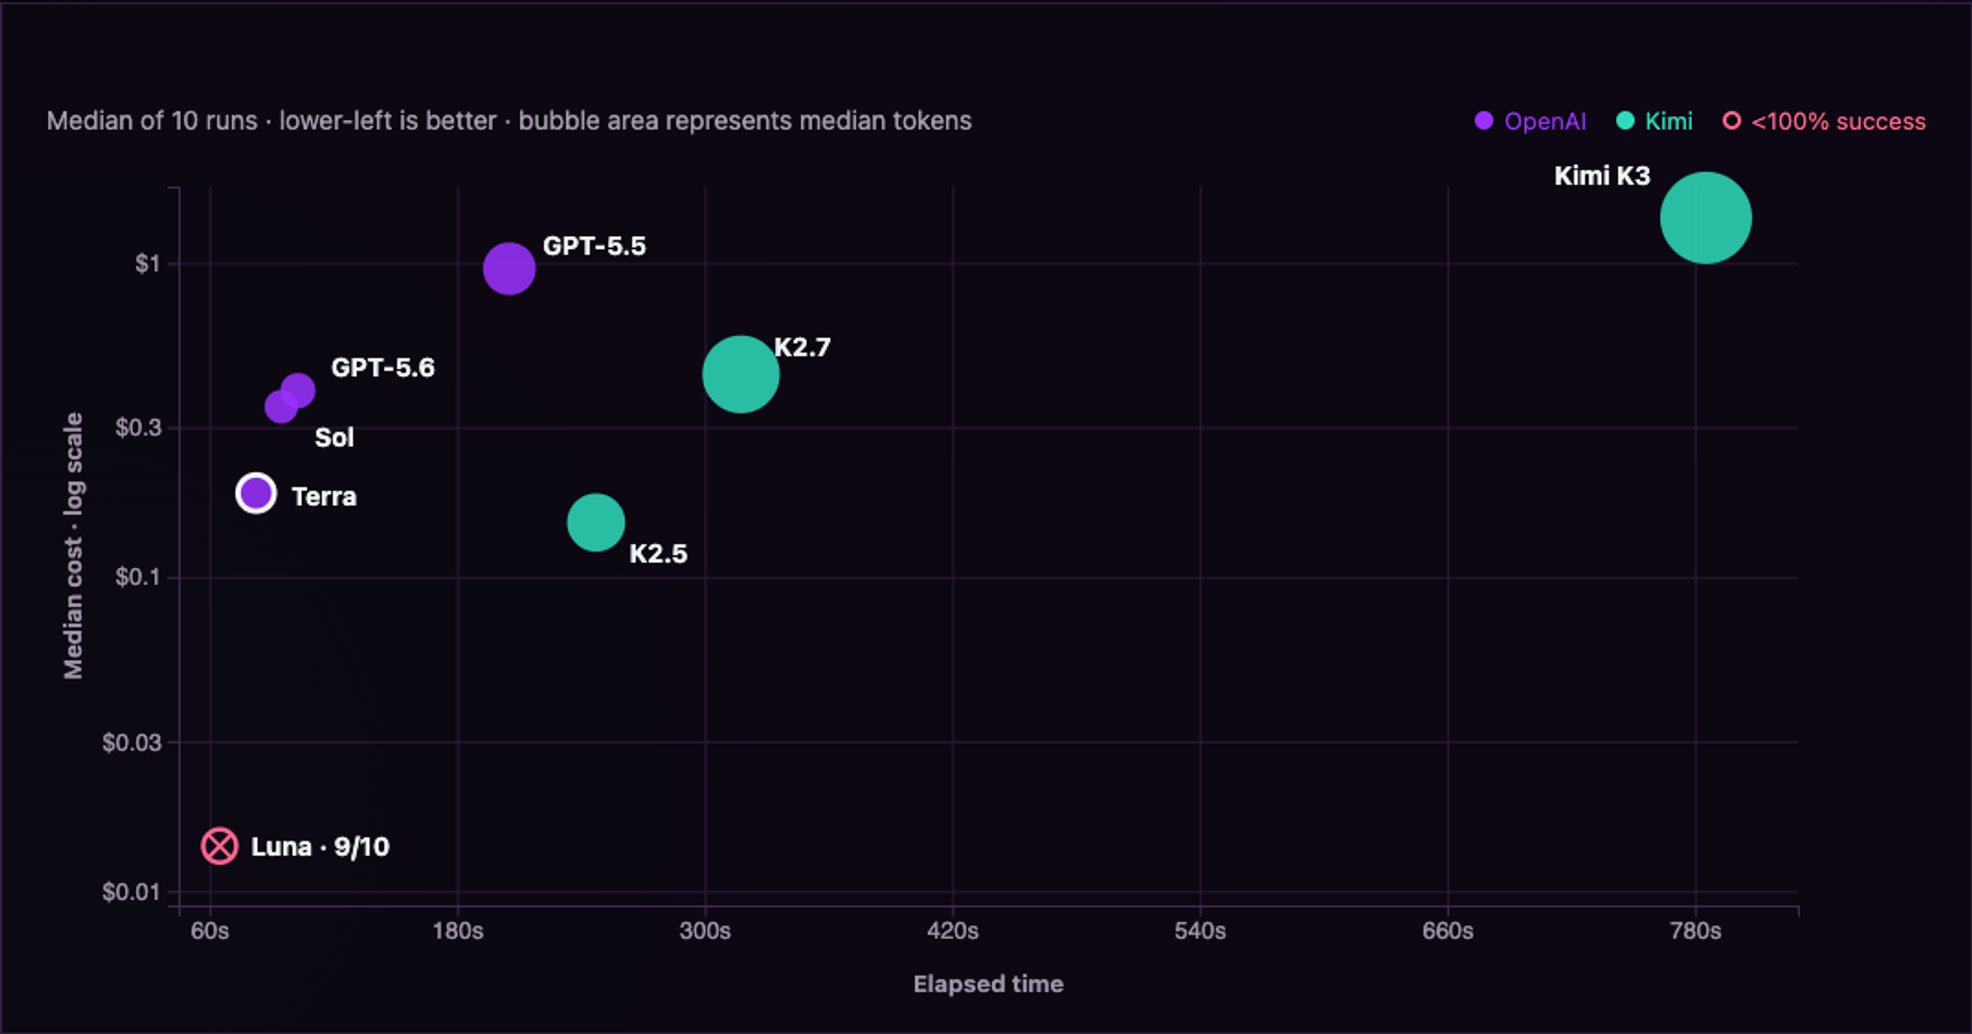
Eight models ran the same five-user login task 10 times. We measured authentication success, cost, latency, tokens, and execution strategy.
Eight models ran the same five-user login task 10 times. We measured authentication success, cost, latency, tokens, and execution strategy.
What two real authorization traces showed us about persistence, restraint, and the evidence gates Tahr needs around both.
Insight: Model choice changes how hard an agent pushes before evidence promotion.
Most AI security systems constrain every attack agent. We take a different approach: let some agents explore widely, then rely on a downstream verifier to keep only what is real.
Insight: Exploration and verification work better when different agents own each job.